Describe the outcome and the boundary
An agent is useful when a task has several steps: gather information, draft an artifact, check it and hand it off. Begin with a narrow outcome, such as preparing a weekly customer-issue summary. List the systems it may read and write. Separate actions that are reversible from those that are not. Reading support tickets and drafting a report is different from issuing refunds or changing account permissions. Start with read-only access wherever possible.
Write a step-by-step workflow with an expected artifact at each stage. For example: retrieve tickets from the defined week, remove personal identifiers, group recurring issues, draft a summary, verify counts against the source and submit it for review. Specify how the agent should behave when a source is unavailable or results conflict. An empty answer is safer than a fabricated total.
Put gates where mistakes matter
Require human approval before sending a customer message, moving money, deleting a record or changing production code. Show the proposed action, its evidence and the exact target in the approval screen. A vague “continue” button does not provide meaningful oversight. Give the agent a time limit, a maximum number of tool calls and a way to stop it. Log what it read, what it changed and why it chose the next step.
Test the workflow with ordinary cases, incomplete data and an adversarial instruction hidden in a document. The agent should treat retrieved text as task data, not as a new authority that can override its rules. Check whether it asks for help at the intended checkpoint.
Measure the completed job
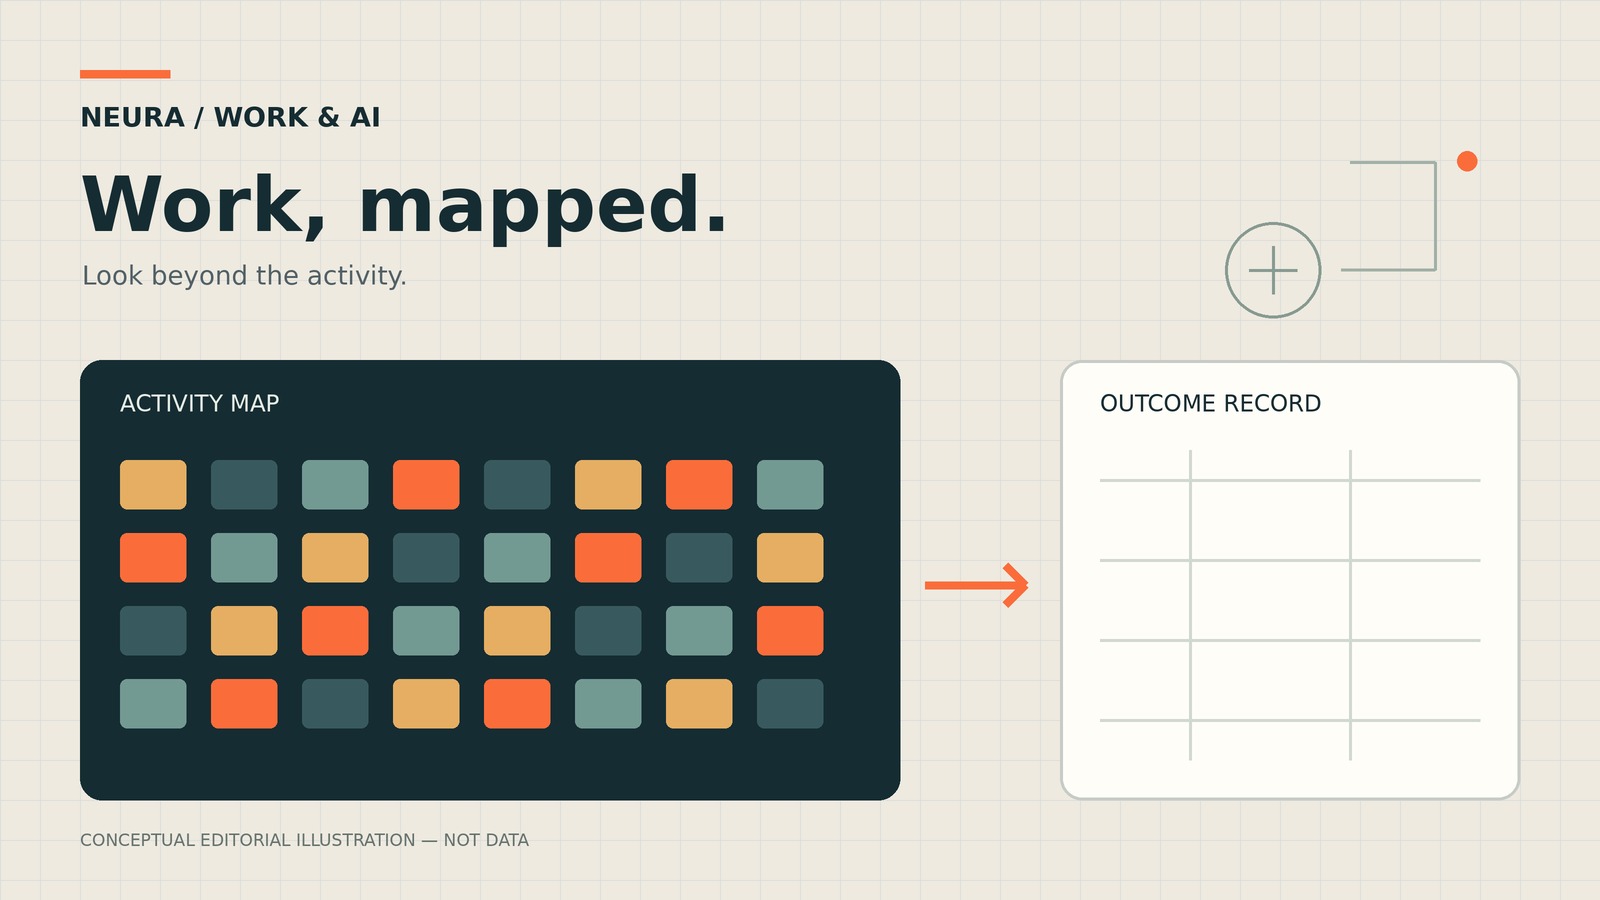
Track correct outcomes, rework, incidents and human review time—not simply how many steps ran autonomously. A well-designed agent may pause frequently at first. Once the failure patterns are understood, some low-risk gates can be relaxed. Preserve a rollback path and an owner who can investigate errors. Autonomy is not the goal by itself; dependable work within clear boundaries is.